How to Build a Content Operating System From Scratch
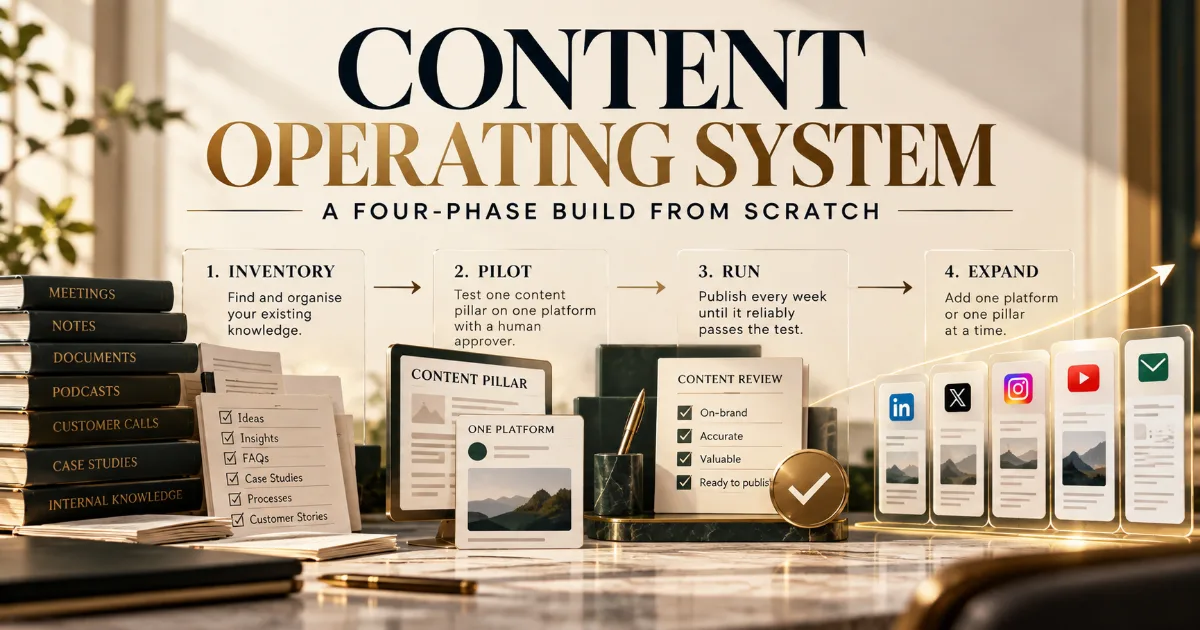
Nobody builds a Content Operating System well by switching everything on at once: the build that works runs in four phases. First you inventory what the business already knows. Then you pilot one pillar on one platform with one approver, run that pilot until it passes an exit test, and only then widen one platform or one pillar at a time. The order exists to prevent the big-bang build, where every pillar, platform and workflow is designed before a single approved piece is published, and nothing ever tests the design.
The four phases of a from-scratch Content OS build
- 01Inventorylist where the business’s knowledge already lives
- 02Pilotone pillar, one platform, one approver
- 03Pilot runrun it every week until the exit test passes
- 04Widenadd one platform or one pillar at a time
- What a from-scratch build looks like when it works
- Why from-scratch builds stall
- Phase one: inventory what the business already knows
- Phase two: one pillar, one platform, one approver
- The exit test each phase has to pass
- Phase four: widen one platform or one pillar at a time
- What the rollout automates, and what stays with a person
- Worked example: a veterinary clinic, inventory to second platform
- What a phased build costs, phase by phase
- Frequently asked questions
- Where to start
What a from-scratch build looks like when it works
A from-scratch Content OS that works goes live in four phases, and each phase ends with a test it has to pass before the next one is allowed to start. Phase one produces a list of where the business's knowledge already lives. Phase two turns one slice of that list into the smallest system that publishes for real. Phase three runs that small system every week until it is dull, and phase four adds one platform or one pillar at a time until the whole shape is in place.
What a from-scratch build stands on
- 01What already exists
questions answered, proposals written, calls recorded
- 02The inventory
a list of where the business’s knowledge lives
- 03The pilot
the smallest system that publishes for real
- 04The whole shape
every pillar and platform, added one at a time
"From scratch" is the misleading part of the phrase. It almost never means starting from nothing, because a business that has customers already answers questions, writes proposals, records calls and explains its work every week. What it lacks is a system that captures that material and turns it into content. So the build starts from an inventory of what exists, and the pillars, the voice and the strategy are read off that inventory instead of being invented in a workshop before anyone has looked.
This post is about the order of the build and the tests between the steps, not about the parts. If you want to know what a Content OS is, our guide on what a content operating system is covers it. The ten stages a finished system contains are written up in how to build a content automation system, and the layers they sit in are in the post on the architecture of a content operating system.
Why from-scratch builds stall before anything publishes
Most from-scratch builds stall because the whole system is designed before any of it publishes, so no decision in the design is ever tested by a real piece of content. Five pillars are agreed in a meeting, six platforms are chosen because competitors are on them, and a long voice guide is written from adjectives. Then the workflows are built to serve all of it at once. By the time the first draft appears, a dozen decisions sit underneath it, and when the draft is wrong nobody can tell which decision caused it.
What the big-bang build decides too early, and what replaces it
The big-bang buildThe smallest version
Five pillars agreed in a meeting
pillars read off material the business already produces
Six platforms chosen because competitors are on them
one platform, the simplest version that does the real job
A long voice guide written from adjectives
a voice checked against a real reader first
A full week of pieces for the approver at once
only as much as one person can approve
The second cost lands on the person who approves the content. A big-bang launch asks them to review a full week of pieces across every platform in the first week, written in a voice nobody has checked against a real reader. They fall behind in the second week, the queue grows, and pieces either wait for days or go out with a lighter look than they should. The system did not fail on capability. It failed because it asked one person for more attention than the business had ever given content before, all at once.
Engineers who build with AI have learned the same lesson in their own work. Anthropic's guide to building effective AI agents recommends "finding the simplest solution possible, and only increasing complexity when needed." A content system is a set of connected workflows with a model in the middle, so the advice transfers almost word for word. Start with the smallest version that does the real job, and add to it only when it has earned the next piece.
There is a quieter version of the same mistake: choosing the pillars before the inventory. Pillars chosen from what a business would like to be known for tend to run dry within a month, because nobody in the building can talk about them every week. Pillars read off the material a business already produces do not run dry, because the material keeps arriving whether or not anyone posts.
Phase one: inventory what the business already knows
Phase one is a written list of where the business's knowledge already lives, who owns each source and what it is good for, and the pillars are read off that list rather than decided before it. Nothing is built in this phase and nothing is published. The point is to find out what the system will have to work with, because a content system can only be as specific as the material it is fed.
When a subject in the inventory is a pillar
A pillar
- 01Several sourcesmaterial on the subject in more than one source
- 02An ownersomeone who can talk about it
- 03Monthly questionsquestions arriving about it every month
a strong candidate the pilot can use
Look in the places where the business explains itself without thinking of it as content. The sent folder of whoever answers customer questions is usually the richest single source. Proposals and scoping documents show how the business describes its own work. Recorded sales calls, onboarding sessions and internal training hold the reasoning that never gets written down, and recorded talks or webinars are often already half transcribed, since YouTube's automatic captioning uses speech recognition to create captions for uploaded videos. Add the FAQ page, the handouts given to customers and the notes kept by the most experienced person on the team.
Write each source down with four facts: what it is, where it lives, who owns it, and what kind of knowledge it holds. Nielsen Norman Group's guide to content inventory and auditing draws the line that matters here: an inventory lists what you have and its characteristics, while an audit judges quality. Phase one is an inventory of knowledge, not an audit of published posts. If the business has a back catalogue worth judging, that is a separate job, covered in how to conduct a content audit, and it can wait.
The pillars come out of the list when you sort it by subject. A subject with material in several sources, an owner who can talk about it, and questions arriving about it every month is a pillar. A subject that appears once, or only in the founder's ambitions, is not one yet. The longer method for testing candidates is in how to identify your knowledge pillars. For the rollout, two or three strong candidates with evidence behind them are enough, because the pilot will use exactly one.
Phase two: one pillar, one platform, one approver
Phase two builds the smallest system that publishes for real: one pillar from the inventory, one platform, and one named person who approves every piece. Choose the pillar with the deepest material behind it, not the one that sounds most impressive. Choose the platform where the audience already pays attention and the business already posts, so the pilot is judged against something familiar. Choose an approver who knows the subject well enough to catch a wrong claim and who has protected time every week to do it.
How one piece moves through the pilot
- 01The source routeMaterialnew material arrives from the inventory every week
- 02DraftingDraftsdrafts are produced from that material
- 03The approverReviewone named person approves every piece
- 04The platformPublishthe approved piece goes out on the one platform
Write the voice and the strategy only as far as the pilot needs them. The voice note for a pilot is a short page built around ten or so real pieces the business has already written, because examples carry tone better than adjectives do. Anthropic's prompting best practices call examples "one of the most reliable ways to steer Claude's output format, tone, and structure." The strategy for a pilot is a single page too: who this pillar is for on this platform, what each piece should leave them able to do, and how often it goes out.
Keeping the material small is not only about saving time. Research on long inputs, "Lost in the Middle: How Language Models Use Long Contexts", found that models perform best when the relevant information sits at the beginning or end of the input, and worse when it is buried in the middle. Anthropic's engineering team describes good practice in its post on effective context engineering for AI agents as "finding the smallest possible set of high-signal tokens." A forty-page voice guide written before the pilot is the opposite of that.
Then connect one source route to the pillar. Pick the source from the inventory that produces new material every week, so the pilot never waits for someone to have an idea. Drafts are produced from that material, reviewed by the approver, and published on the one platform. If you would rather have the pilot built than build it yourself, it has the same shape as our single-platform system, which covers one platform from knowledge capture to approved publishing.
The exit test each phase has to pass
A phase is finished when it passes a test that was written before the phase started, not when the team feels it is done. Writing the test first is what stops a phase from drifting on for months, and it is also what stops a rushed phase from being declared complete because everyone is tired of it. The idea is old. The PDSA cycle described by the W. Edwards Deming Institute has you plan with a prediction, do the work, study the result against the prediction, and act on what you learned.
How a phase earns its exit
write the test before the phase starts
run the phase against that test
read the result against the test and the platform’s own numbers
fix the one stage that failed
| Phase | It passes when | It has not passed if | What you hold at the end |
|---|---|---|---|
| 1 · Inventory | Every source has a location and an owner, and two or three candidate pillars each point to material in several sources | A pillar rests on one document, or on what the founder hopes to be known for | The written inventory and a shortlist of pillars |
| 2 · Pilot setup | One draft from the real source route has been approved and published, start to finish, on the chosen platform | The pipeline only works on a test topic someone typed in by hand | A one-page voice note, a one-page strategy and a working route |
| 3 · Pilot run | Several weeks in a row: the queue fills from the source, the approver clears it on time, nothing goes out unapproved, and the edits keep getting smaller | A week was skipped, a piece went out unseen, or the approver is rewriting rather than editing | A pilot that runs without anyone pushing it |
| 4 · Each widening step | The new platform or pillar passes the same run test while the pilot keeps passing it | The pilot's own numbers or approval times slipped when the new part arrived | One more part, and a system that still behaves |
Phase three, the pilot run, gets no section of its own because its whole content is that row of the table. The system runs every week on the one pillar and the one platform, and the only work is watching it. The test is deliberately boring. When several consecutive weeks pass without a gap, without an unapproved piece and with lighter edits each time, the voice note and the strategy have been checked against real readers and the approver's time has been proven to exist.
Each test also needs a reading of what the content did, taken from the platform's own numbers. For a website that means Google's Search Console Performance report, which counts clicks and impressions from Google Search. How to decide which numbers count, and how long to wait before trusting them, is covered in how to measure whether a content system works. When a phase fails its test, fix the one stage that failed and run the test again. Widening a system that has not passed only spreads the failure.
Phase four: widen one platform or one pillar at a time
Phase four widens the system by adding exactly one thing at a time, either one platform or one pillar, and each addition needs its own groundwork before it switches on. Adding two at once brings back the big-bang problem on a smaller scale: when something breaks, you cannot tell which addition broke it. One at a time also keeps the approver's load growing in steps they can absorb.
How phase four adds one thing at a time
While the pilot runs
One pillar, one platformthe run test passes week after week
The first addition
One new platforma short note on what is native there, then the run test again
The next addition
One new pillarits own evidence and its own examples in the voice note
By the last step
The team runs iteach step is run more by the business’s own team
A new platform needs a short note on what is native there, covering format, length, how often it goes out and what that platform's own rules allow. It needs the approver's time again, because a new format reads differently even on a familiar subject. The cheapest second platform is usually one that can reuse the pilot's source material in a new shape, which is the job of a content repurposing workflow that does not create generic content. A new pillar needs its own evidence from the inventory and its own examples in the voice note, because the tone that works on aftercare may not work on pricing questions.
Phase four is also when the system changes hands. The pilot was run with whoever built it close by; each widening step should be run more by the business's own team, so that by the last step the people who own the system are the ones operating it. That is the difference between a system you own and a service you rent, which we set out in content operating system vs content agency. Every widening step reruns the phase-three test, and the pilot has to keep passing it while the new part settles in.
What the rollout automates, and what stays with a person in each phase
The line between automated and human work moves as the rollout goes on, but approval stays with a named person in every phase. In the inventory, automation can transcribe recordings, pull documents into one place and sort sources by subject. A person decides which sources are accurate, which knowledge is safe to publish, and which subjects deserve to be pillars, because those are judgements about the business and not about the text.
Who holds the work by the end of the rollout
- Automated transcribing, drafting, formatting, scheduling and collecting the numbers
- A person the pillars, the voice note, the strategy and reading the numbers
- Approval a named person in every phase
The shape of the problem, not a measurement
In the pilot, drafting and formatting can be automated from the source route, while the voice note, the one-page strategy and the approval stay human. In the pilot run, scheduling, reminders and collecting the numbers can all run without anyone touching them. Reading those numbers and deciding what to change is still a person's job. In the widening phase, adapting a piece to a new platform's format is automatable, but the decision to widen, and what to add next, belongs to whoever owns the system.
The general version of this line, applied to content work as a whole, is set out in what to automate in your content and what not to. The rollout adds one thing to it: the automated share grows phase by phase as each piece earns trust, and nothing becomes automatic before the test for its phase has been passed with a person watching.
Worked example: a veterinary clinic, from inventory to second platform
Here is the rollout for an independent veterinary clinic, built in Claude Code and n8n. It is an illustration rather than a client: the clinic is invented, and nothing in it is a measured result. We chose it because a clinic's knowledge is real, specialised and already being explained every day, mostly to worried pet owners at the reception desk and in follow-up emails.
The clinic’s weekly workflow, from reception questions to approval
Collect gathers the questions reception has tagged
Sort files them under preventive care
Read connects documents on the clinic’s shared drive
Voice note adds the reception team’s best replies
The drafts wait for the lead vet, held by the Wait node until the approval form arrives
The inventory took the reception team's sent folder, the aftercare handouts given after procedures, the vets' consultation note templates, and a recorded talk one vet gave to a puppy class. Sorted by subject, three candidate pillars stood out: preventive care, recovery after procedures, and caring for older pets. Preventive care had the most material and the most repeat questions, so it became the pilot pillar. The platform was Instagram, where the clinic's clients already followed it, and the approver was the lead vet, with a fixed slot at the end of each week, because a wrong claim about an animal's health is the kind of mistake the clinic cannot afford.
The working folder lives in Claude Code. The inventory sits in it as plain files, the voice note is built around a dozen of the reception team's best replies, and two skills do the drafting, each a SKILL.md file as described in Claude Code's documentation on extending Claude with skills. Documents still kept on the clinic's shared drive could be connected rather than copied, using the Model Context Protocol, the open standard for connecting AI applications to data sources and tools.
The weekly cycle runs in n8n. Each week it collects the questions reception has tagged, sends them to the drafting skill, and posts the drafts to the lead vet. Then it stops: n8n's Wait node documentation describes a node that pauses a workflow until it receives a form submission, which is the vet's approval. Each platform's publishing steps sit in their own sub-workflow, following n8n's guide to breaking workflows into smaller parts, so a later platform can be added without touching the pilot.
After the pilot had run cleanly for several weeks, the first widening step added the clinic's website, on the same preventive care pillar, with longer answers built from the same reception questions. That was one new sub-workflow and one new note on what a website answer needs. The second step, still to come in this example, would be a second pillar on Instagram, recovery after procedures, with its own examples added to the voice note. Our page on Instagram content automation covers what a full system on that platform involves, and the Instagram guides collect what we have written about it.
What a phased build costs, phase by phase
A phased build costs less attention per week than a big-bang build but more patience, and the expensive part is the approver's time, not the software. The inventory costs a few conversations with the people who hold the knowledge and someone willing to dig through old folders. The pilot setup costs the drafting of two short documents and the wiring of one route. Neither is large, and both are easy to rush.
Where the cost of a phased build sits
Relative, not measured
The pilot run is where the real cost sits. It needs the approver every week, on time, for weeks in which nothing new is added, and that is hard to protect when the system looks finished. The usual month-two failure is that the approver slips, the queue backs up, and someone proposes adding a second platform to make the effort feel worthwhile. The right response is the opposite: hold the pilot until it passes again. Each widening step then costs a small setup and a fresh run of the test, so the full shape takes longer to reach than a launch would, but it arrives working.
If you build it with outside help, the work is what a content automation specialist does: design the phases, build the routes and hand the system over. A pilot on one platform is the single-platform setup on our pricing pages, while the full shape, every pillar and platform the business needs, is a content operating system built around your business. Tools such as n8n and the model you draft with are billed by their vendors, separately from any build.
Frequently asked questions
Can a business with no published content build a Content OS?
Yes, because the system is built from what the business knows, not from what it has already published. A business with customers answers questions, writes proposals and explains its work every week, and those sources are what the phase-one inventory collects. Published posts are useful if they exist, but they are one source among many, and often not the best one.
Which pillar should the pilot use?
Use the pillar with the deepest material behind it in the inventory, the one that appears across several sources and keeps generating new questions. That pillar will not run dry during the weeks the pilot has to run. The most impressive-sounding pillar is often the thinnest, because it reflects what the business wants to be known for rather than what it talks about every day.
Why start a Content OS on only one platform?
Starting on one platform means every problem in the first weeks has one possible cause, and the approver has one format to learn. With several platforms live at once, a weak draft could come from the voice note, the strategy, the platform format or the source, and nobody can tell which. One platform also keeps the approver's weekly load small enough to be met reliably.
Who should approve the content in a phased rollout?
The approver should be one named person who knows the subject well enough to catch a wrong claim and who has protected time for it every week. In a specialist business that is usually the most senior practitioner on the pilot pillar, not a marketing assistant. Approval stays with a named person in every phase, including after the system has been widened and handed over.
Do we need a full brand voice guide before the pilot starts?
No. The pilot needs a short voice note built around ten or so real pieces the business has already written, and that is enough to draft one pillar on one platform. A full guide written before any content is approved is a set of guesses about how the business should sound. The pilot run turns the short note into a tested one, and it grows as each pillar is added.
What happens if the pilot fails its exit test?
Fix the one stage that failed and run the test again, without widening. If the queue is empty, the source route is the problem; if the approver is rewriting drafts, the voice note or the strategy is. A failed test is useful, because it points to a single cause while the system is still small enough to change cheaply.
When is a Content OS ready to hand over to the team?
It is ready when each part has passed its test with the team, rather than the builder, operating it. Handover happens gradually through phase four: each widening step is run more by the business's own people, so by the last step the team already runs every route, holds the documentation and knows what to do when a test fails.
Where to start
This week, start the inventory list, and nothing else. Open a document, and for every place the business already explains itself, write what it is, where it lives, who owns it and what kind of knowledge it holds. Begin with the sent folder of whoever answers customer questions and the recordings nobody has listened to since. When the list is long enough to sort, sort it by subject and see which two or three subjects keep coming back. That is the evidence your first pillar will stand on, and it costs nothing but an afternoon. When the list is done, the rest of our content operating system guides cover what each later phase builds.
Disclosure
This post was written by Shreyas Dave, founder of Paper Eagle AI. We sell content automation services, which is the category this article is about, so we have a commercial interest in you concluding that a system beats ad-hoc effort — read it knowing that. No tool vendor was involved in writing it, nobody paid for a mention, and there are no affiliate links anywhere on this site. Where a third-party figure appears, it’s attributed to the publisher it came from; anything we couldn’t source is written as a direction rather than a number.
Paper Eagle AI builds Content Operating Systems that turn a business’s knowledge and expertise into consistent, multi-platform content, and we deliver them as content automation services. Working as a content automation specialist, we capture what a business knows and how it sounds, set the strategy, and build the workflows that research, draft, repurpose and publish — with a named person approving every piece before it goes out. Every build runs through discovery, design, build and handoff. The system lives in the client’s own accounts, it is documented, the team is trained to run it, and the business owns it outright. We don’t write content on a retainer, and we don’t build lead generation, CRM or sales automation.
One source of thinking becomes native content for every platform a business publishes on: the founder’s LinkedIn and the company page, YouTube and Shorts, Instagram and Reels, TikTok, Reddit, Medium, newsletters, and the company’s own website, written to be found in Google and understood by AI search. Our multi-platform content automation page shows how they share one source, and our case studies document the systems behind our own publishing, file by file. You can follow the work on the company’s own channels: Paper Eagle AI on Instagram, Paper Eagle AI on YouTube, the Paper Eagle AI company page on LinkedIn, Paper Eagle AI on Substack, Paper Eagle AI on Reddit and Paper Eagle AI on Medium.
Keep reading
- How to Build a Content Automation System From Scratch — the ten stages a finished system contains, in build order.
- What Is a Content Operating System? — the definition, and why the operating-system metaphor fits.
- What to Automate in Your Content, and What Not To — where the line between machine and person goes once the system is running.